XUNYE Services · COMPUTE & DEPLOYMENT
Compute & Deployment
Three independent options — pick one.
Deploy a complete system in your own environment; rent dedicated compute; or call open models through an API.
Three options
Based on your needs, choose one of three services.
The three services are independent — pick the one that fits, or start with the three questions below.
Compute build-out & private deployment
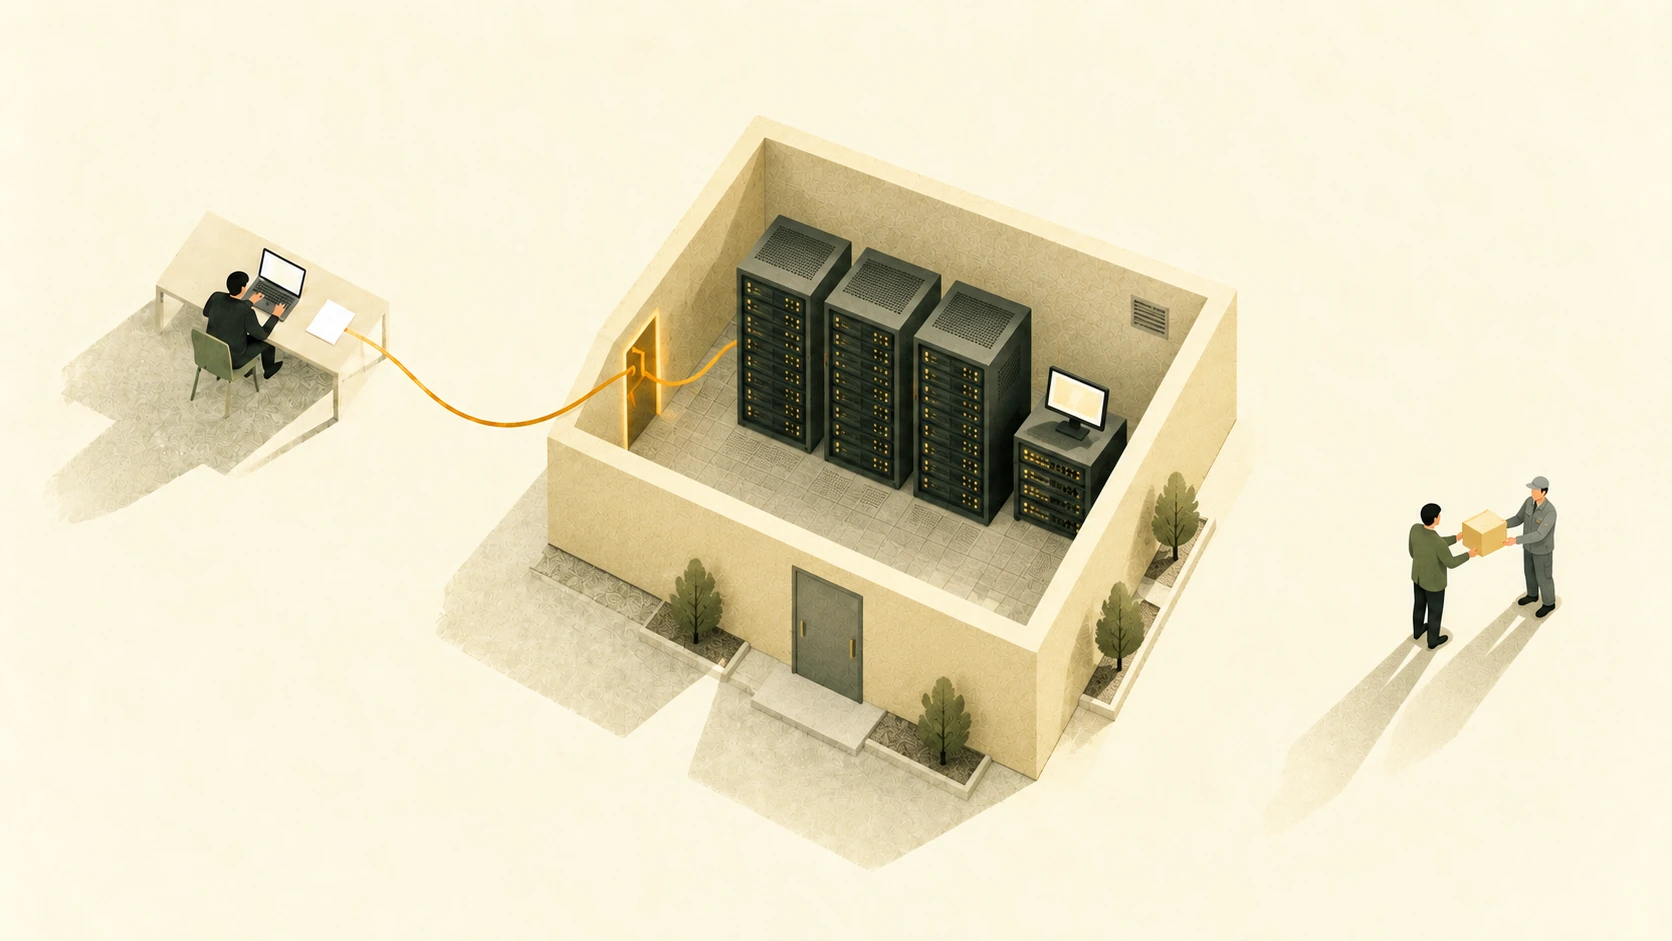
A complete, working system — validated on real tasks and delivered on your site.
Who it fits
Teams that want equipment, models, and applications running inside their own environment.
What we do
We plan the configuration around your tasks and concurrency, help with equipment selection or adaptation, then deploy the models and applications and validate them on real tasks before handover.
What you receive
- Configuration and implementation plan
- A deployed system validated on real tasks
- Acceptance records and permission setup
- Operation and maintenance documentation
Ongoing operations can be agreed separately.
Implementation scope
Configuration ranges from reusing existing servers to a new server room or cluster, sized to actual needs. Equipment can be procured with our help or purchased by you with us handling adaptation; networking, power, cooling, and site works are assessed per project. Deployment can cover inference services, knowledge bases or agents, and business applications, with training and handover at delivery.
Dedicated compute rental
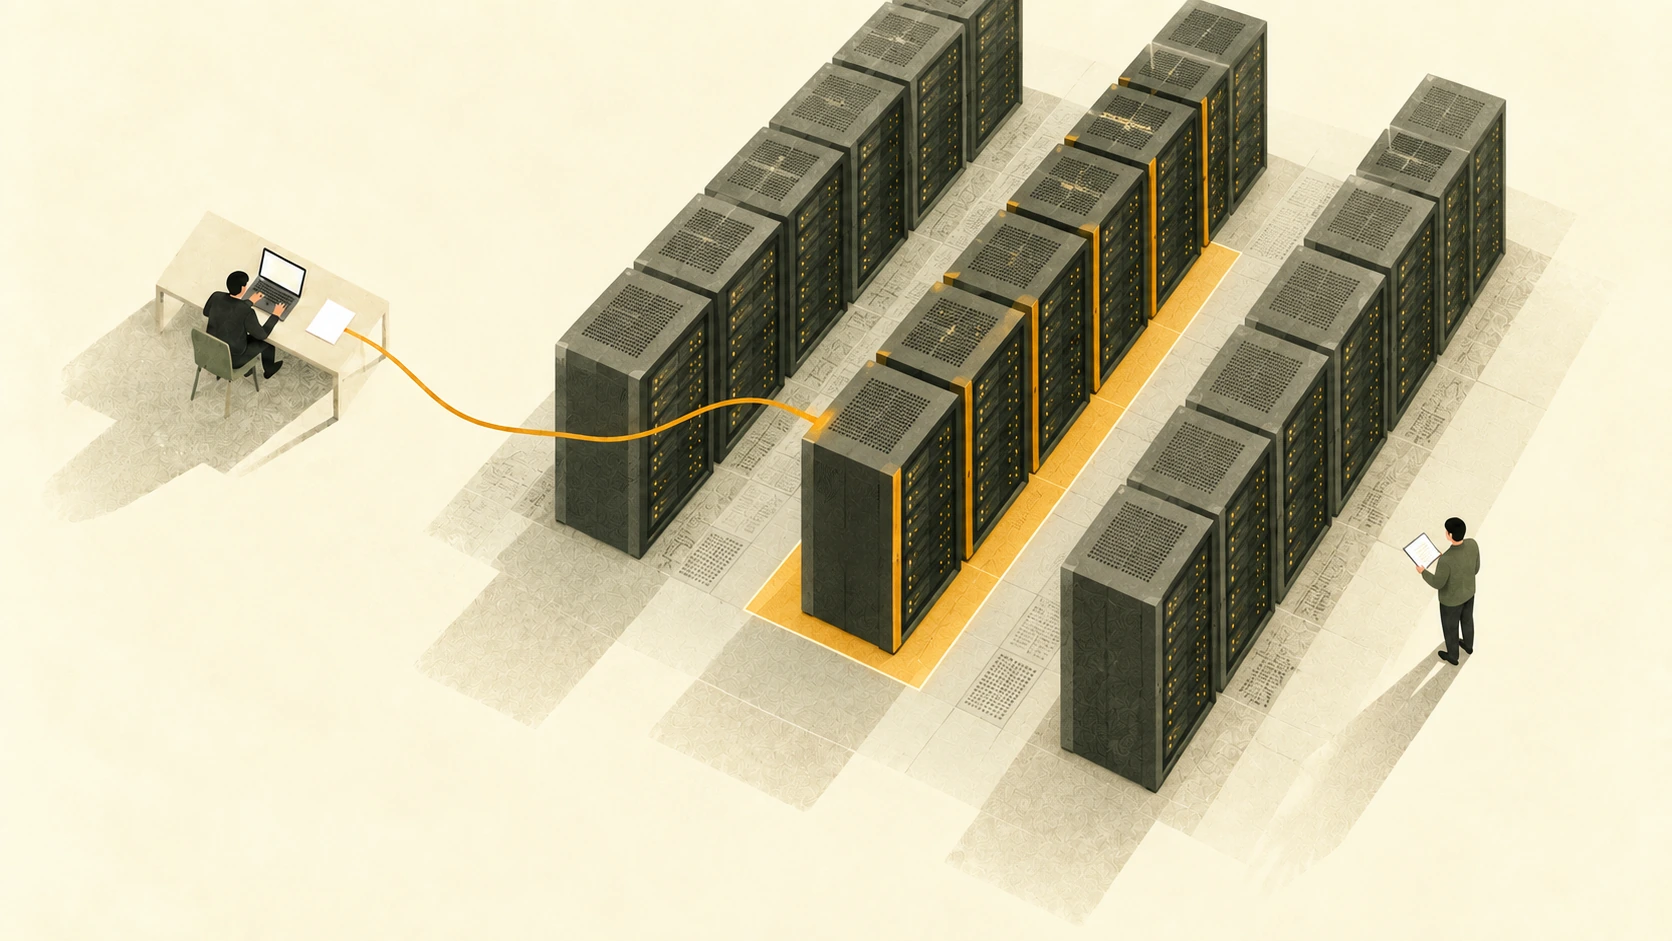
A dedicated remote compute environment for the rental period — self-deployed, or set up by us.
Who it fits
Teams that would rather not buy equipment but need working GPU servers or clusters.
What we do
Once specifications, rental period, and access are agreed, we deliver a dedicated remote compute environment; you deploy everything yourself, or ask us to set it up.
What you receive
- The agreed compute resources
- Access configuration and usage guide
- Optional deployment and operations services
Isolation, access control, and operations authorization are designed per project.
Implementation scope
Resources are yours for the rental period, with specifications, term, and access agreed up front. Model installation, runtime environments, application debugging, and continuous operations are optional services, agreed separately and never silently bundled into the rent. Remote dedicated resources start quickly and are managed differently from a fully on-premises deployment.
Open-model API services
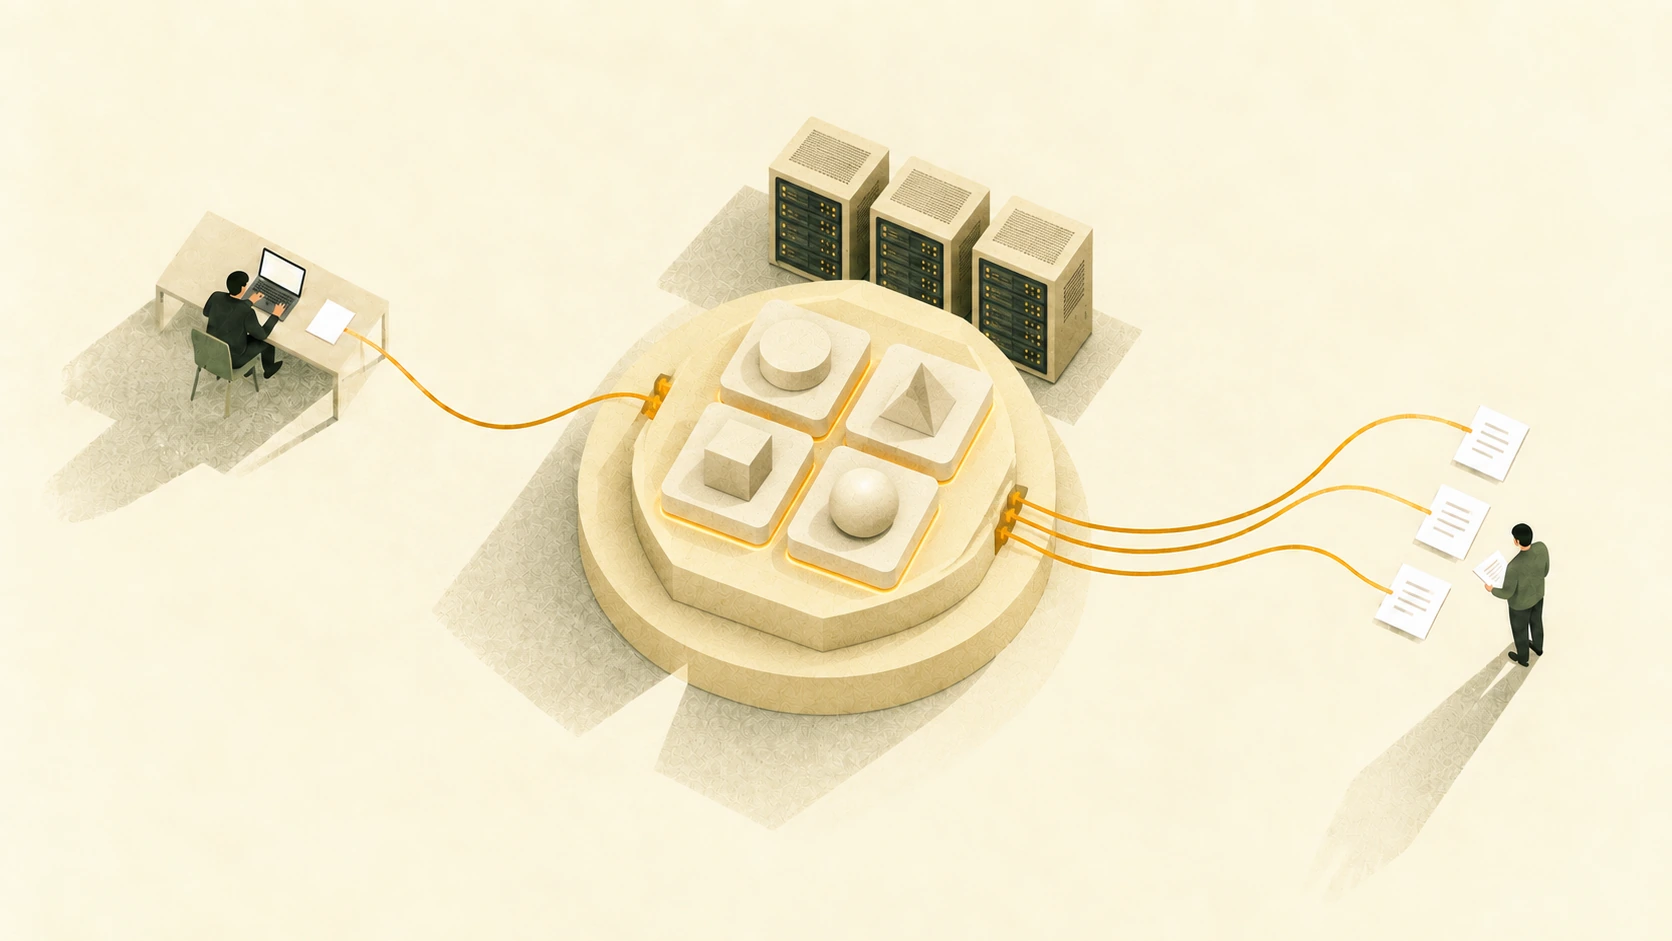
Call open models such as DeepSeek, GLM, Qwen, and Kimi — we maintain the servers.
Who it fits
Teams that would rather not run models themselves.
What we do
We deploy and maintain open versions of the DeepSeek, GLM, Qwen, and Kimi families and support integration and joint testing; you call the capability over the agreed interface and never manage a server.
What you receive
- Integration guide and API configuration
- Joint testing records
- Usage records
The model runtime and API service are maintained by us.
Implementation scope
Available families and versions are confirmed by task, resources, and licensing terms; the interface and integration plan are defined in the proposal. Billing follows the agreed call volume or plan; text models can be metered by input and output tokens, with usage records available.
See the optional open-model series for families you can call.
Quick pick
Unsure? Start with three questions.
-
Equipment and data must stay in your environment?→
Option 01, on-premises: runs at your site; the delivered system is yours to own and operate.
-
No equipment purchase, but you want control of models and apps?→
Option 02, dedicated rental: resources sit with us, dedicated to you for the term — you decide what runs on them.
-
You just want model capability inside your apps?→
Option 03, open-model API services: models and servers stay with us; you only make the calls.
Still unsure? Contact us with your tasks and current environment.
Open models
Optional open-model series
We can shape deployment and API service selections around open versions of the DeepSeek, GLM, Qwen, and Kimi families. Specific versions are confirmed by task, resources, and licensing terms; the directions listed are selection guidance.
-
DeepSeek
Reasoning and analysis, math, and code.
Official repository -
Zhipu GLM
Tool calling, code, and agent tasks.
Official repository -
Tongyi Qwen
General dialogue, content processing, and multilingual tasks.
Official repository -
Kimi
Tool use, reasoning, and complex task collaboration.
Official repository
Choose the model→Deploy & integrate→Call the API
After launch
After launch, someone stays responsible.
Operations support
Fault response and version upgrades as agreed.
Team training
Built on our AI training programs.
Scale as needed
Reassess resources as tasks and users grow.
Related: Knowledge bases & agents · Enterprise agent systems · MuseFlow content creation
FAQ
Using the services, and working together.
01We already have servers — can we use them?
Start with an assessment: reuse what supports the target models and concurrency, and fill the gaps. Not every project needs a new server room.
02Do we have to buy equipment from you?
No. Purchase yourself and we handle adaptation, or we help you choose and procure — agreed per project.
03After renting compute, who deploys the models?
Your choice: your team deploys, or we set up models and environments for you — scoped and agreed separately.
04Renting compute vs. calling the open-model API?
Renting gives you the servers for the term — you decide what runs on them. The API gives you the model capability itself, with the infrastructure maintained by us.
05Can a local deployment run offline?
It depends on whether models, software, and dependencies are fully installed on site; we test and confirm the offline scope before handover.
06How are data and permissions handled?
Isolation, access control, logging, and operations authorization follow your data categories and deployment location; confidential scenarios are assessed separately.
07How are costs composed?
Private deployment by equipment and implementation; rental by specification and term; open-model API services by agreed volume or plan — all per the assessed proposal.
08What is a token?
The unit models use to read input and produce output; text services can be metered by input and output tokens.
Contact XUNYE
Tell us the task — we pick the option together.
Share your tasks, environment, and timeline; we confirm the right option and scope through a needs assessment.